Training and Using Embedded Models in Stable Diffusion
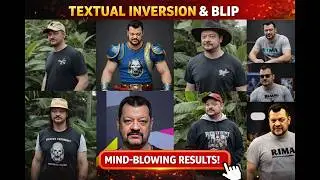
Stable Diffusion textual inversion training is the easiest way to get the model to generate you—and in this video I walk through the full beginner workflow using an embedding trained on images of myself. If you’ve ever wondered why base models don’t “know” your face, this tutorial shows exactly how to fix that inside AUTOMATIC1111.
We start by editing the Web UI user file and reviewing the command line arguments I use to run Stable Diffusion. Then we download the Stable Diffusion 1.5 prune safetensors model from Hugging Face and place it in the correct models folder so we can train at the right base level. From there, we prep training photos by making sure I’m the only person in the images, then resize everything to 512x512 using Birme (the preferred resolution for 1.5 training).
Next, we create a unique embedding name, set vectors per token to 12, pick a prompt template, and configure training fields based on the dataset size. After training begins, we review the first training snapshot and then test the embedding across different 1.5 models to compare results. I also show why the embedding won’t work on XL models when it was trained on 1.5, and what that means for your workflow.
⭐ Like & Subscribe
If this helps you, hit 👍 and subscribe 🔔 — it really supports the channel.
💸 Support & Bonus
Some links below are affiliate links, which help support the channel at no extra cost to you.
Amazon: https://amzn.to/4kRpXQk
Robinhood: https://join.robinhood.com/travisb-70...
🔑 Keywords / Hashtags
stable diffusion textual inversion, textual inversion training tutorial, train embedding stable diffusion, stable diffusion embedding training, AUTOMATIC1111 textual inversion, stable diffusion webui embedding, stable diffusion 1.5 safetensors download, runwayml stable diffusion v1-5, resize images 512x512 stable diffusion, birme resize for stable diffusion, vectors per token 12, prompt template textual inversion, train your face stable diffusion, stable diffusion embeddings for beginners, stable diffusion 1.5 training workflow, why embedding not working on SDXL
#stablediffusion #textualinversion #automatic1111 #stableDiffusionWebUI #embeddingtraining #aigeneratedart #aimodel #safetensors #huggingface #birm e #sd15 #aiarttutorial #generativeai #text2image #homelab
⏱️ Chapters
00:00 Intro
00:31 Web-UI Settings
01:45 Download Training Model
02:38 Place Safe Tensor File in Folder
03:11 Edit Textual Inversion File
04:53 Prepare Images
05:43 Birme
06:38 Create the Embedding
08:12 Set Training Fields
11:17 First Training Image
12:00 Testing different models
14:42 Like and Subscribe
Auf dieser Seite können Sie das Online-Video Training and Using Embedded Models in Stable Diffusion mit der Dauer stunde minuten sekunde in guter Qualität ansehen, das der Benutzer MadTc Tech 30 Juni 2024 hochgeladen hat, den Link mit Freunden und Bekannten teilen, dieses Video wurde auf Youtube bereits 2,965 Mal angesehen und es wurde von 38 den Zuschauern gefallen. Viel Spaß beim Betrachtenden Zuschauern gefallen!